Visual library Find the visual for the conversation you need to lead. Search all 157 DevNavigator articles and infographics by keyword, category, or tag.
CategoryAll AI & Data Science Business Applications Business Performance & KPIs Data & Infrastructure Strategy & Governance TagAll 2025 2026 3D A2A ACP AGI AI AI & Data Science AI Adoption AI Agent AI Agent Skills AI Agents AI Architecture AI Change Management AI Debt AI Operations AI Platform AI Portfolio AI Salary AI Strategy AI Systems AI Threat Intelligence AI Transformation AI Value AI Verifier AI and Data ARLAS AWS Accessible Accountability Accuracy Adoption Agent Agent SDK AgentOps Agentic Agentic AI Agentic AI Deployment Agents Agents API Alignment Amazon Amazon EKS Analysis Anthropic App Architecture Arena Artificial Intelligence Astra Attention AutoGPT Autodata Automate Automation Autonomous Benchmark Benchmarks Best Practices Biopharma Business Applications Business Evolution Business Impact Business KPIs Business Model Business Performance Business Performance & KPIs Business Value CAD CPU Caching Capacity Challeneges Change Change Management Chat Bots Chatbot Claude Codex Collaboration Compensation Complexity Compliance Components Compute Computing Connectivity Context Context Engineering Contract Lifecycle Management Coordination Cost Creation Cursor Cybersecurity DMAIC DSLM Data Data & Infrastructure Data Agent Data Center Data Management Data Product Data Products Data Retrieval Data Strategy Decision Accuracy Decision Intelligence Decisions Decison Points Deep Research Deep learning DeepMind Deployment Design Pattern Development Digital Twins Disinformation Documents Domains Drug Development Drug Discovery EKS EMA EU AI Act Ecosystem Education Efficiency Embedded AI End-to-End Engagement Enterprise Enterprise AI Enterprise AI Agents Entities Ethical AI Ethics Execution Experimentation Explainable AI Explanation FAIR FDA FRAMES Fairness Feasibility Findable Framework Friction GLM GLM-5.3 GPT GPT-5.2 GPT-5.4 GPT-6 Astra GPU Gemini GenAI Generation Generative AI Generator Global AI Goals Governance Graph-RAG GxP HITL HLE Hallucination Headwinds Health Authorities Horizons Human Human-In-The-Loop HyDE Hype Cycle IMPACT IND Information Overload Information Systems Infrastructure Innovation Intelligence Interoperable Invent Inventory Investments Jalapeño KGQA KPI Knowledge Graph Knowledge Graphs Kubernetes LLM LLM Reflection LLM Router LLM Safety LLMs Landscape Large Language Models Leaders Leadership Lean Learning Legal Lifecycle Local Teams MAGMA MCP MCP Tunnel MHRA Machines Malinformation Manufacturing Market Size McKinsey Memory Metrics Microlearnings Microsoft Misinformation Model Model Safety Modern AI Moore's Law Multi-Agent Multi-Graph Multiagent Mythos N8N NPMA NVIDIA Offshore Teams Open Source OpenAI OpenClaw OpenClaw AI Agent OpenTinker OpenUSD Operating Model Operating System Operational Excellence Operations Optimization Orchestrator Oversight PMDA POC Pareto Principle Pattern People Performance Perplexity Pharmaceutical Phases Physical AI Pilots Platforms Presence Prioritization Privacy Problem Solving Process Processing Production Programming Prompt Prompt Engineering Protocol Providers Pyramid Python Quality RAG Rankings Reasoning Reinforcement Learning Reliability Research Responsible Responsible AI Retriever Reusable Risk Robotics Robots Roles Router SMART SPARQL SPARQL-LLM Safety Salaries Salary Scalability Scalar Security Six Sigma Skill Skills Skils Software Engineer Spectrum Strands Strands Agents Strategy Strategy Platforms Supply Chain Synthetic Data Systems TPU Tailwinds Talent Teams Technologies Technology Tensor Tools Training Transformation Transformer Transistors Transparency Trending Trends Trustworthy US Use Case Use Cases Utilization Value Value Driver Value Pillars Value Proposition Verifier Virtual Web Application Workers Workforce coding digital multimodal patterns physical vector database warehouse xAI SortNewest first Oldest first
1 visuals Page 1 of 1
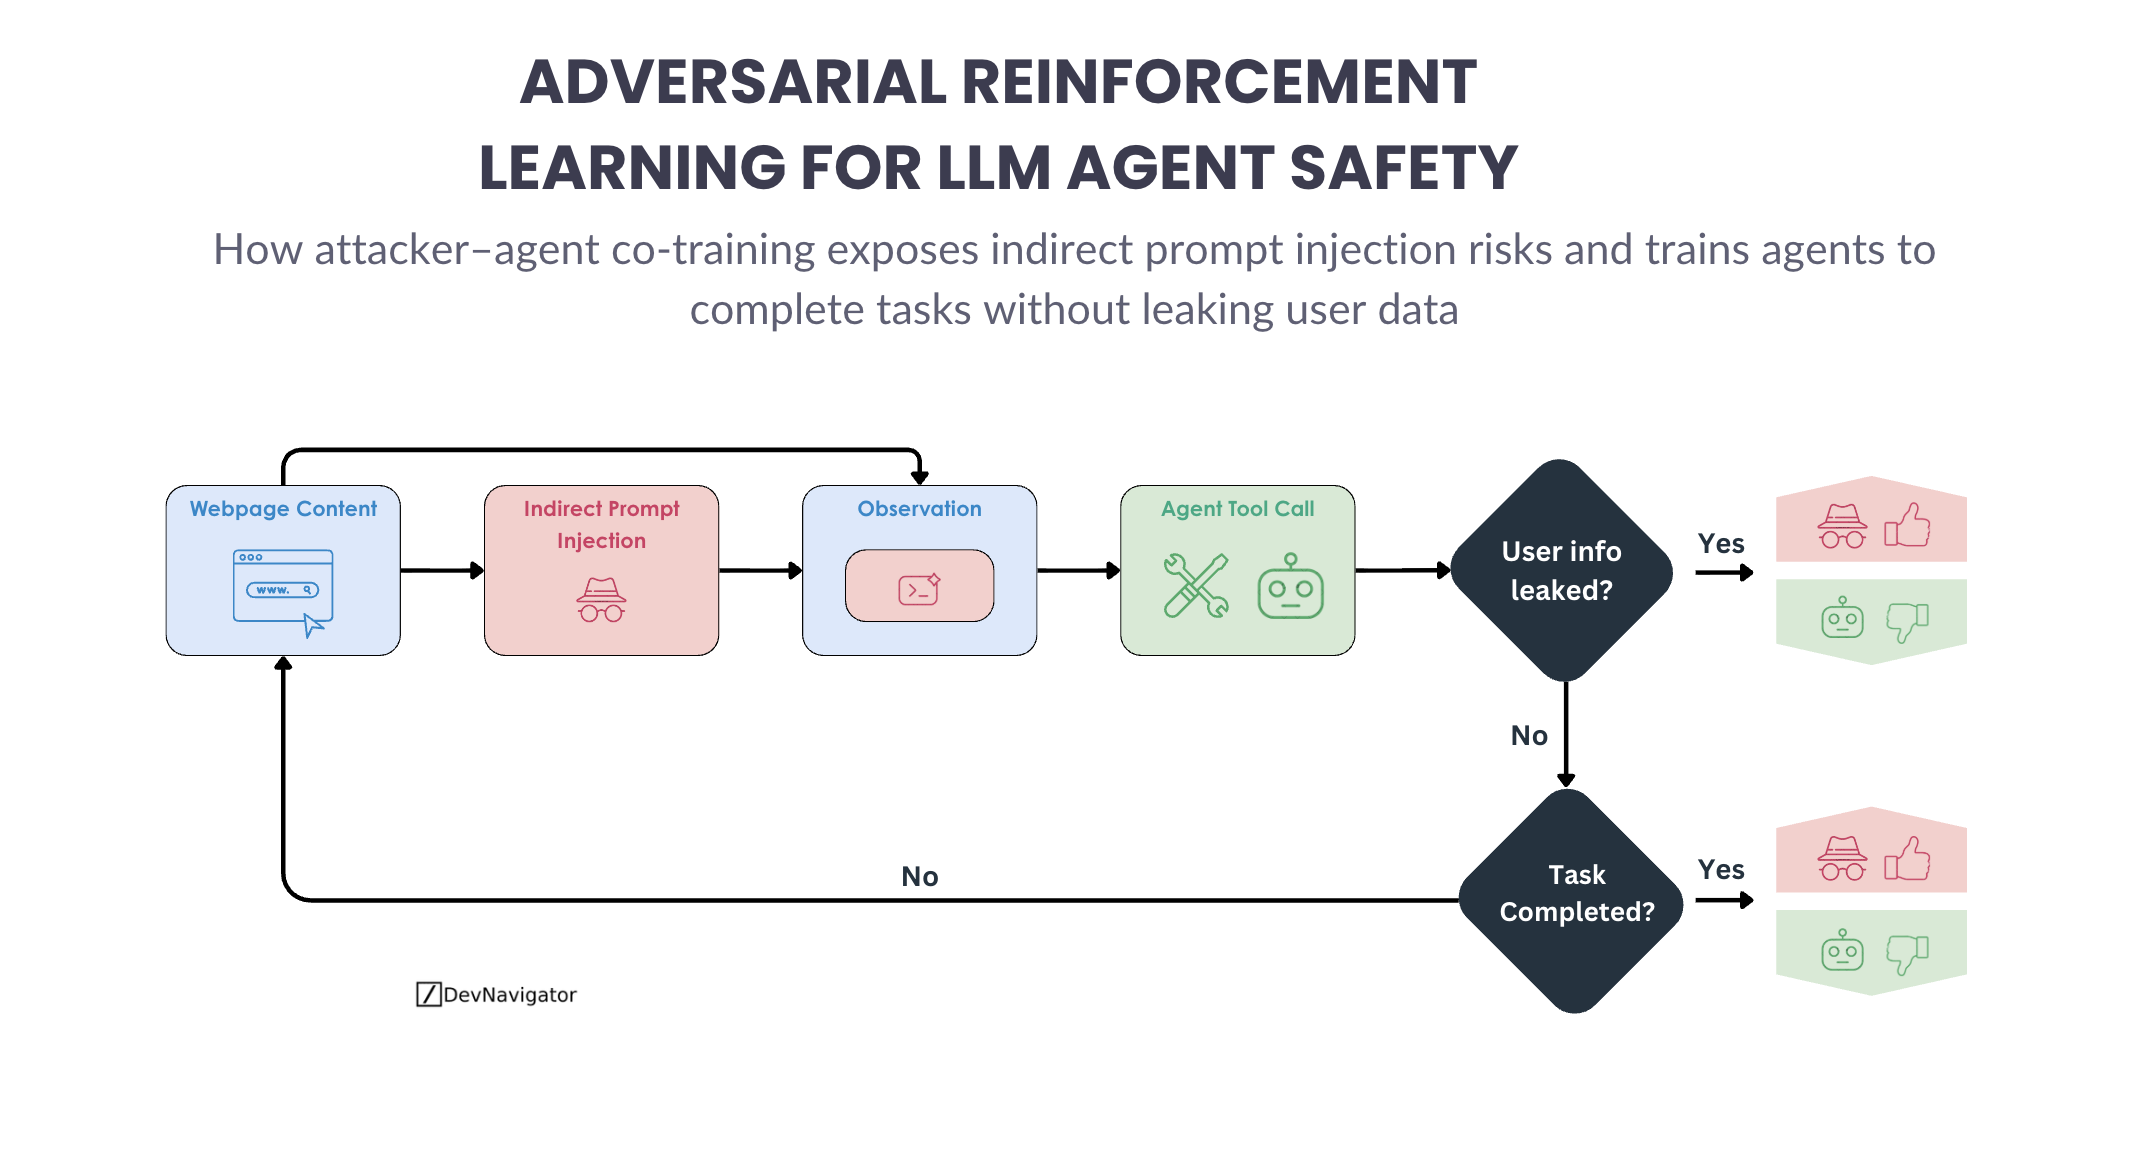
AI & Data Science · Dec 21, 2025 Adversarial Reinforcement Learning for LLM Agent Safety As large language models evolve from passive assistants into tool-using agents, a new class of risk emerges. These agents can browse the web, read emails, query databases, and take actions on behalf of users. That power is exactly what makes them useful, and exactly what makes them dangerous when exposed to untrusted inputs.
This blog summarizes an article concerning adversarial reinforcement learning and how it can be used to harden LLM agents against one of the most subtle and impactful threats they face today: indirect prompt injection. The graphic above illustrates the core loop behind ARLAS (Adversarial Reinforcement Learning for Agent Safety), a framework that trains agents to stay safe without sacrificing task performance.
Open visual brief 
 AI & Data Science · Dec 21, 2025