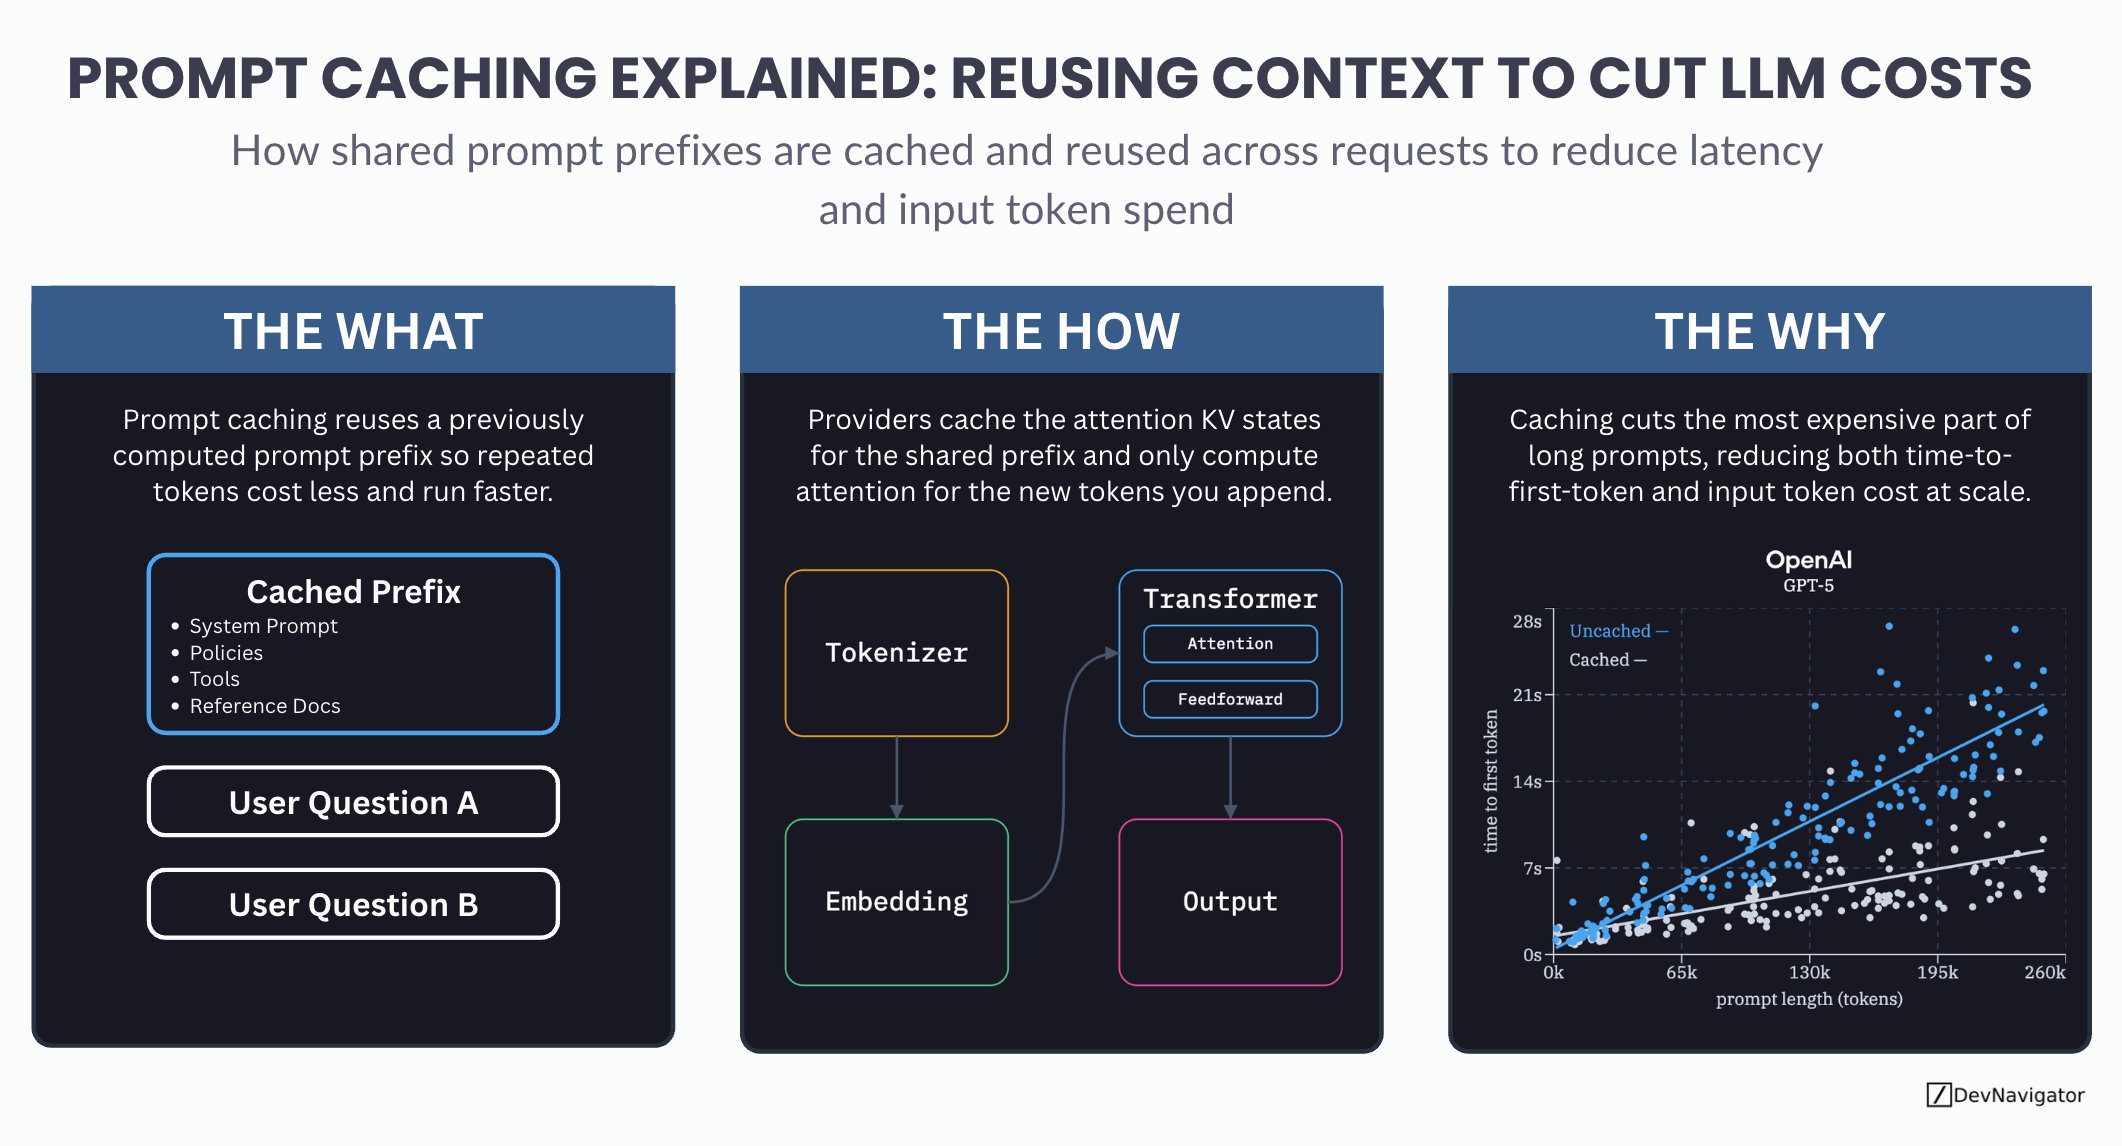
AI & Data Science · Dec 25, 2025Prompt Caching Explained: A Smarter Method for Reusing Context to Cut LLM CostsPrompt caching is one of the most important cost and performance optimizations quietly shaping modern LLM applications. As teams scale agents, RAG pipelines, and long-context workflows, the same large prompt prefixes are often sent to models again and again. Prompt caching exploits this repetition, allowing providers to reuse previously computed context instead of recomputing it from scratch on every request. The result is faster responses and dramatically lower input token costs.Open visual brief
 AI & Data Science · Dec 25, 2025